When a Mnemonic Cues the Wrong Word: Separate It in Space
A chimpanzee may have something surprisingly useful to teach us about learning vocabulary. When a mnemonic cues the wrong word, the problem may be that memory needs another dimension—such as space, direction, or movement—to separate two competing answers.
In 2007, researchers Sana Inoue and Tetsuro Matsuzawa reported an experiment with chimpanzees using a touchscreen. Arabic numerals appeared at different positions on the screen. The animals had learned to touch them in numerical order. Then came the interesting part: after the first numeral was touched, the remaining numerals disappeared behind identical white squares. The chimpanzee now had to remember not only the numbers, but where each of them had been. PubMed – Working memory of numerals in chimpanzees.
A young chimpanzee named Ayumu became famous for his performance.
In a more demanding version of the task, five numerals selected from 1 to 9 appeared briefly and were then masked. At the shortest exposure, only 210 milliseconds, Ayumu achieved about 79 percent accuracy. Nine human participants tested on the same task did not approach that performance.
That result produced memorable headlines.
But there is an important second part of the story.
Ayumu had received extensive practice. The original human participants had not. Later experiments showed that humans given substantial practice could match, and in another study even surpass, his performance.
That correction does not make the experiment less interesting.
For me, it makes it more interesting.
It changes the question from:
“Are chimpanzees simply better at this than humans?”
to:
What if the important lesson is not that chimpanzees performed better on this task, but that our learning methods have gradually separated us from the body and from spatial memory?
What Ayumu’s Memory Test Can Teach Us
Matsuzawa later proposed what he called a cognitive trade-off hypothesis.
He suggested that the impressive immediate visual memory seen in young chimpanzees might reflect a representational system that preserves unusually detailed records of visual scenes. Such a system could be useful in a world where fast decisions about objects and spatial situations matter. By contrast, human cognition became exceptionally powerful at language, abstraction and extracting the general gist of events that can be communicated to other people. OUP Academic
This remains a hypothesis, not a demonstrated evolutionary law. But as a way of thinking about learning, it raises a provocative question.
What have we trained ourselves to ignore?
A chimpanzee moving through a three-dimensional environment cannot afford to treat space as decoration. Distance, direction, position, movement and relationships between objects matter.
Modern humans certainly retain formidable spatial abilities. But much of modern education trains us under very different conditions.
We sit.
We face a page or a screen.
We manipulate symbols.
We listen to explanations.
We repeat words.
We are often taught as though serious thinking happens mainly inside the head, while the body and surrounding space merely transport that head from one lesson to another.
Yet our brains did not become disembodied because schools invented desks.
Vision, hearing, touch, movement and spatial orientation involve partly distinct but heavily interacting neural systems. The brain continually integrates information across these systems rather than processing experience through one single mental channel.
That is a useful clue from nature.
Why reduce a new word to one repeated sound when the brain can represent relationships through sound, vision, movement, position and space?
This is also consistent with the principle I use throughout Saper Vedere: a word can acquire relationships to sounds, images, meanings, situations, movements and lived experience. The richer network provides more possible ways back to the information.
You already experience something similar in ordinary life.
You walk into another room to do something.
Then the purpose disappears.
You stand there wondering why you came.
So you walk back.
And quite often, when you return to the original place, the thought comes back.
The room did not contain the thought like a note pinned to the wall. But the original environment formed part of the context in which the thought occurred. Returning to that context can help restore cues associated with it.
This is more than an everyday anecdote. Memory research has repeatedly shown context dependence, and a recent experiment made the idea especially relevant to language learning.
Participants learned 80 foreign words from two phonetically similar African languages inside virtual environments. When each language was learned in its own distinctive spatial context, interference between the two languages decreased. One week later, retention reached about 92 percent in the distinctive-context condition compared with about 76 percent when both languages had been learned in the same context. The researchers also found that mentally reinstating aspects of the original learning context could support retrieval. Nature
Space is therefore not merely the background against which learning happens.
Space can become part of the cue.
And that brings us directly to a common vocabulary problem.
When a Mnemonic Cues the Wrong Word
Consider two very ordinary English words for a Czech learner:
GIVE = DÁT
GET = DOSTAT
There is already an interesting relationship here.
Both English words begin with G.
And the resemblance on the Czech side is even stronger: dát and dostat both begin with D and end with T. They do not sound identical, but they share the same opening and closing consonants — a compact D…T frame that can make them easier to blend together in memory.
So the learner may notice a perfectly real cross-language pattern:
G → D…T
That is a real pattern.
This is one way a mnemonic cues the wrong word: the cue identifies a family of possible answers but fails to distinguish the target from its competitor.
It is also insufficient.
The pattern tells you something useful, but it still leads to two destinations.
Does G mean give — dát?
Or get — dostat?
This is exactly the kind of problem that repeated sound alone does not solve.
In my earlier book Ovládněte svůj mozek, I used these very words to illustrate the weakness of passive repetition:
give = dát, give = dát, give = dát
get = dostat, get = dostat, get = dostat
Repeated without creating additional relationships, the two items can remain vague and become confused.
There is an important distinction here.
Repeating give can make the sound give increasingly familiar.
Repeating get can make the sound get increasingly familiar.
But repeating a sound does not automatically create a spatial relationship that was absent before.
It does not spontaneously decide:
toward me,
away from me,
above me,
below me,
left,
right,
inside,
outside.
If the missing distinction is spatial, repetition cannot create that missing dimension until you actually add it.
When a mnemonic cues the wrong word for this reason, adding another round of passive repetition simply keeps travelling along the same ambiguous route.
So add it.
Imagine yourself as the person in the middle.
Money comes toward you:
GET
Money leaves your hand and moves away from you:
GIVE
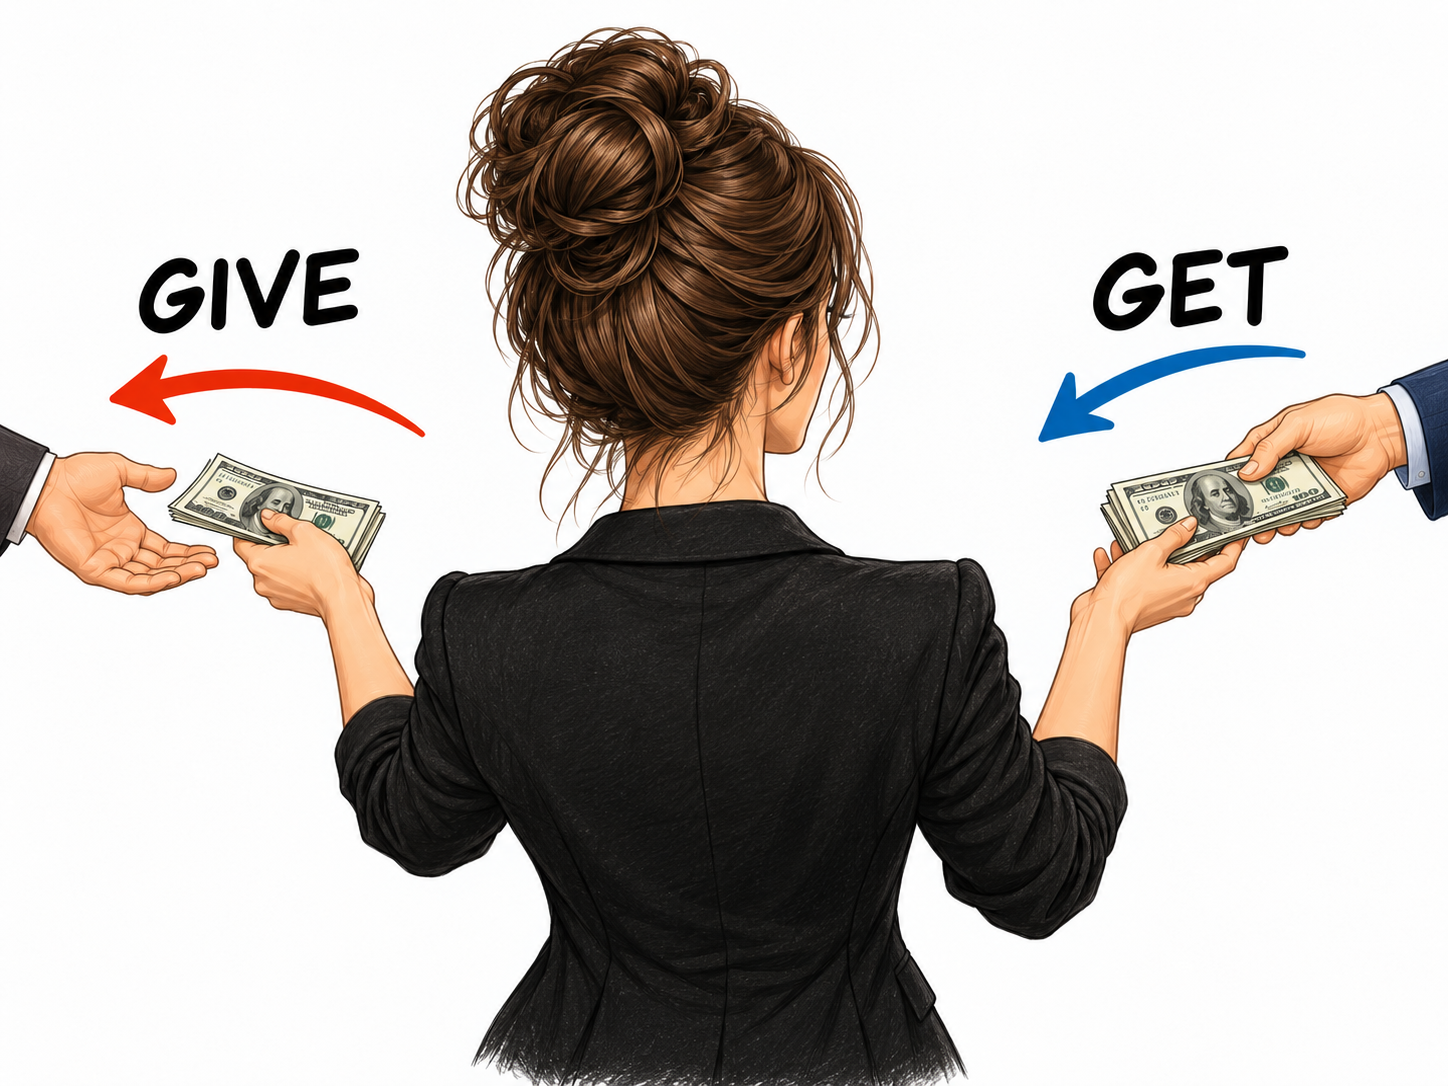
Now the distinction exists in another dimension.
You are no longer relying only on:
G → D.
You have added:
GET → toward me
and
GIVE → away from me
That can be represented with a picture.
It can be represented with arrows.
It can be represented with your hands.
It can be represented by actually passing an object to another person and receiving it back.
The solution does not have to be intellectually impressive.
A seven-second gesture may do more useful work than twenty rounds of passive repetition.
Put Opposites in Opposite Places
Italian gives us an even cleaner demonstration:
salire — to go up
scendere — to go down
Both begin with S.
Both describe vertical movement.
If they have begun to merge in memory, the learner may retain only something vague such as:
“one of those Italian S-words about moving vertically.”
That is not an absence of memory.
When a mnemonic cues the wrong word, ask first whether two competing words have been encoded with too many of the same features.
It is a failure of discrimination.
When a mnemonic cues the wrong word, adding a spatial contrast can give each competitor a different mental location.
So stop trying to solve a spatial distinction with sound alone.
Draw two arrows:
salire ↑
scendere ↓
Then point upward when you say salire.
Point downward when you say scendere.
Better still, involve the body.
Rise when you say salire.
Lower yourself into a squat when you say scendere.
You could even make the contrast absurdly physical: a small jump for salire, a deep squat for scendere.
Now the two words are no longer neighbours sitting on the same verbal shelf.
One has acquired upward space and upward movement.
The other has acquired downward space and downward movement.
This is the principle I want you to notice:
When two words collide in one dimension, separate them in another.
If sound is ambiguous, add position.
If position clarifies the distinction, use position.
If movement makes the distinction unmistakable, move.
If a simple arrow does the job, draw the arrow.
The purpose of a mnemonic is not to demonstrate how imaginative you are.
The purpose is to bring back the right information.
Make the Difference Visible
A great deal of mnemonic advice concentrates on one word:
vividness.
Make the scene bigger.
Brighter.
Stranger.
Funnier.
More emotional.
Those qualities can certainly make something memorable.
But memorability and precision are different problems.
Suppose one mnemonic image already activates two competing words.
Making that image twice as vivid can simply give you a more vivid ambiguity.
The more useful question is:
What does this cue contain that points specifically to this word rather than to its competitor?
That is where Saper Vedere becomes practical.
Looking sees:
salire and scendere are two Italian words beginning with S.
Seeing discovers:
one rises; one descends.
Looking sees:
give and get are two English words beginning with G.
Seeing asks:
What can I add so that my memory experiences receiving and giving as two different directions?
That difference might be spatial.
It might be visual.
It might be a sound feature.
It might be movement.
It might be context.
The repair can be surprisingly small because the goal is not to construct the most elaborate mnemonic possible.
The goal is to find the missing distinction.
There is another lesson hidden in the chimpanzee experiment.
The later human results showed that practice mattered enormously. Humans were capable of becoming far better at the visuospatial task than the original comparison suggested.
That is encouraging.
Perhaps the useful conclusion is not that modern humans have somehow lost the ability to think spatially.
Perhaps we simply spend enormous amounts of time practising other forms of thought.
We practise words.
We practise linear text.
We practise symbols on flat pages.
And then we are surprised when our first response to a memory problem is:
repeat the words again.
But the world around you contains another vocabulary-learning instrument that costs nothing.
Space.
Up and down.
Toward and away.
Near and far.
Inside and outside.
Left and right.
And you carry another instrument everywhere:
your body.
You can point.
Turn.
Reach.
Step.
Rise.
Lower yourself.
Give.
Get.
Learning does not have to remain trapped between your ears.
The next time a mnemonic cues the wrong word, treat the mistake as useful information. It shows you that two mental routes are overlapping.
So when a mnemonic cues the wrong word, treat the error as a map of where your cues still overlap.
Then ask a better question:
What difference could I make visible, audible, spatial or physical so that these two words stop leading to the same place?
Sometimes the answer will require another mnemonic element.
Sometimes it may require a more distinctive sound clue.
And sometimes all you need is an arrow.
If the mnemonic already points to the correct word but still gives you too little grip to retrieve it reliably, continue with Cue-Stacking for Stubborn Vocabulary.
For the broader problem of vocabulary that resists a single memory route, return to When One Mnemonic Is Insufficient.
Memory. Attention. Technology. Creativity. Hypnosis. Together, they spell MATCH.
Libor Činka, author of The Invisible Illusionist, is an Ericksonian hypnotherapist, trainer, and creator of innovative learning methods who has spent over three decades exploring how this unusual combination can make learning more engaging and longer-lasting in memory.
The Curtain Is Up — The English Edition Is Here
The Invisible Illusionist is now available in English, the first language edition. Future translations will depend on reader interest. Leave your email and choose your preferred language to help us decide which edition comes next and receive updates about its availability.